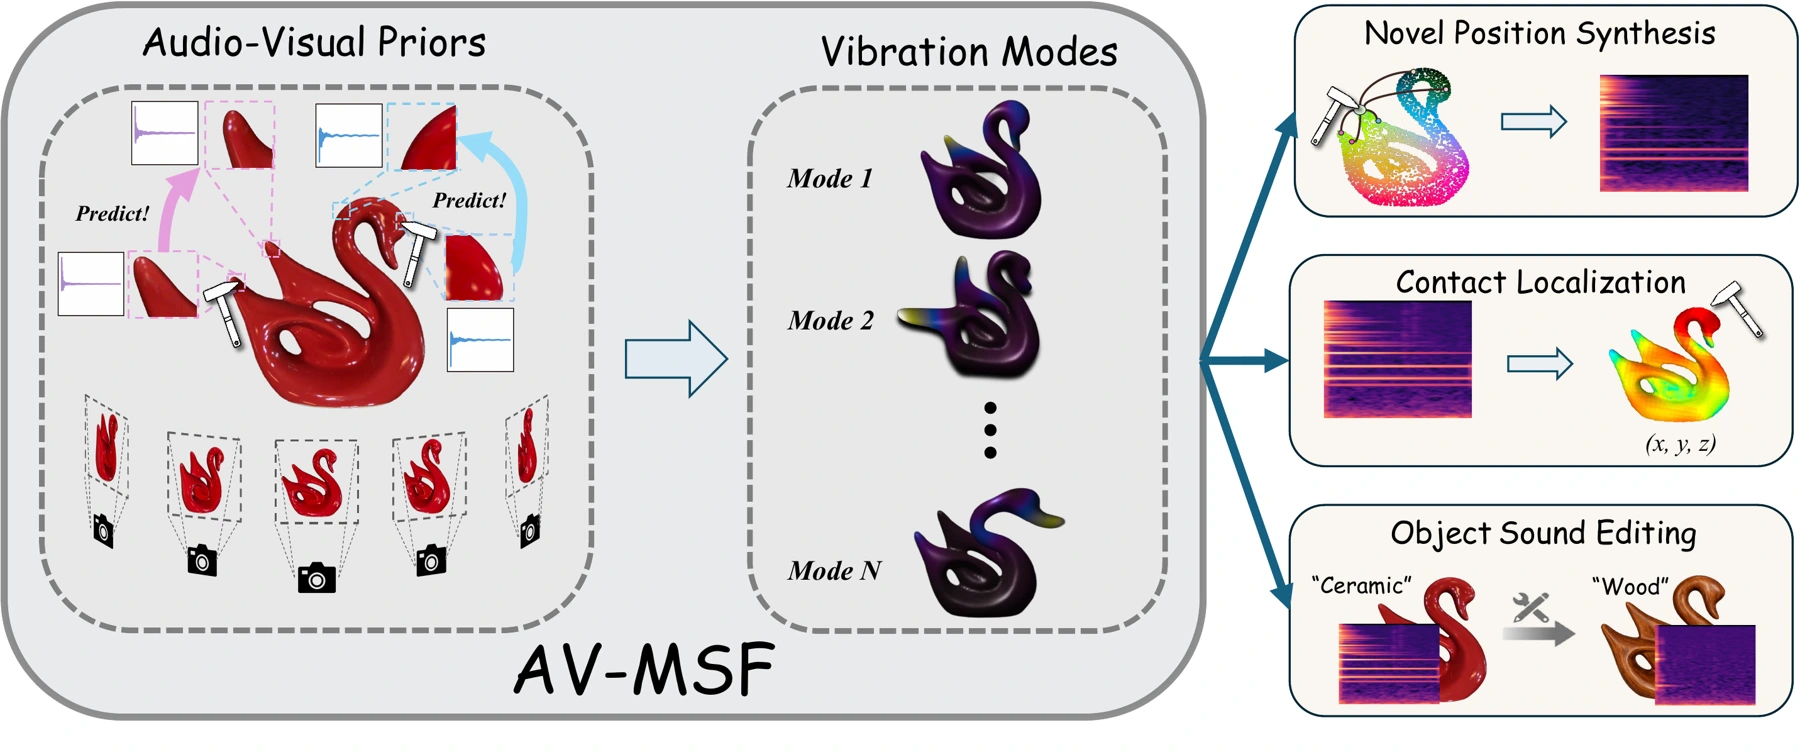
Objects as Audio-Visual Modal Sound Fields
Reconstructing how objects sound from multi-view images and a few impact recordings.
RESEARCH COLLECTION
Exploring visual, audio, and language representations.
* denotes equal contribution. Click a figure to explore the method.
Reconstructing how objects sound from multi-view images and a few impact recordings.
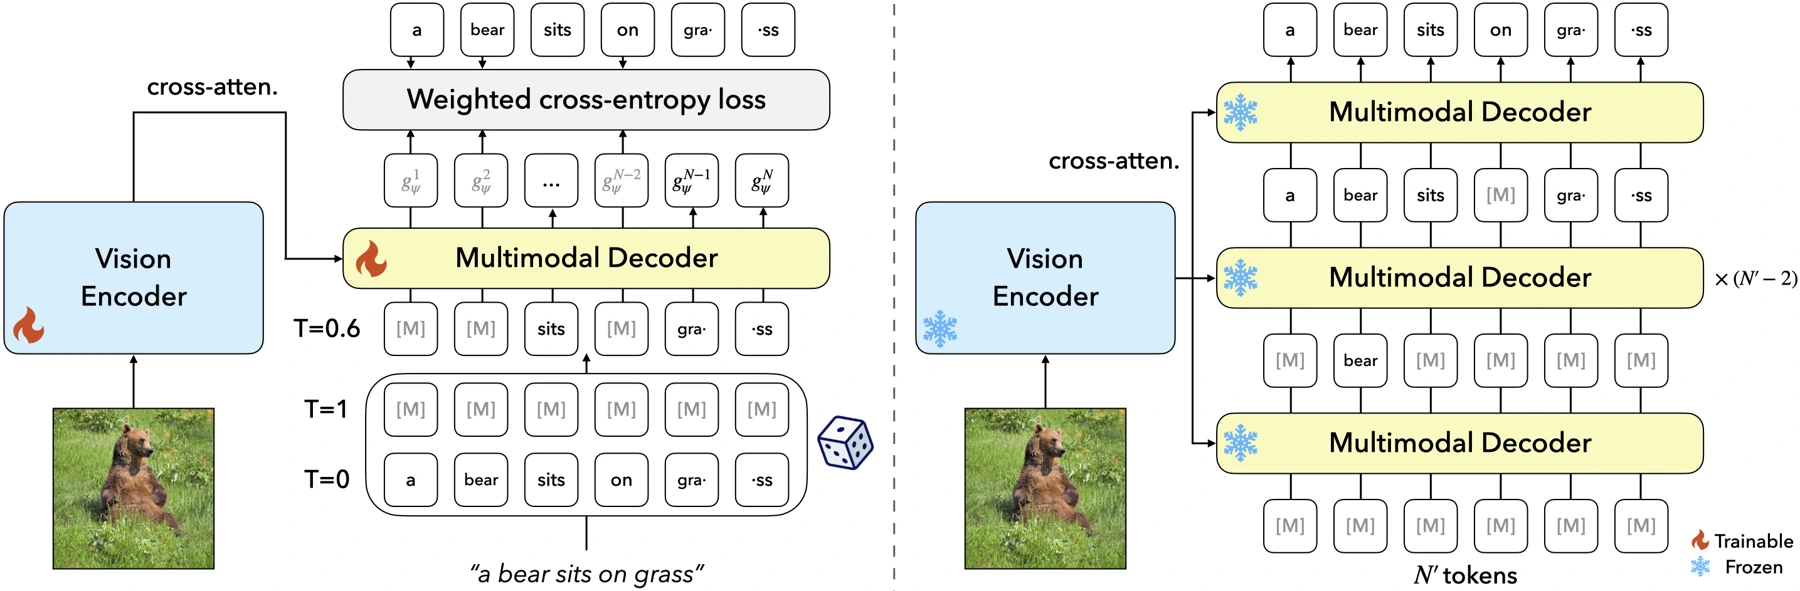
Learning visual representations by reconstructing masked captions with an image-conditioned diffusion model.
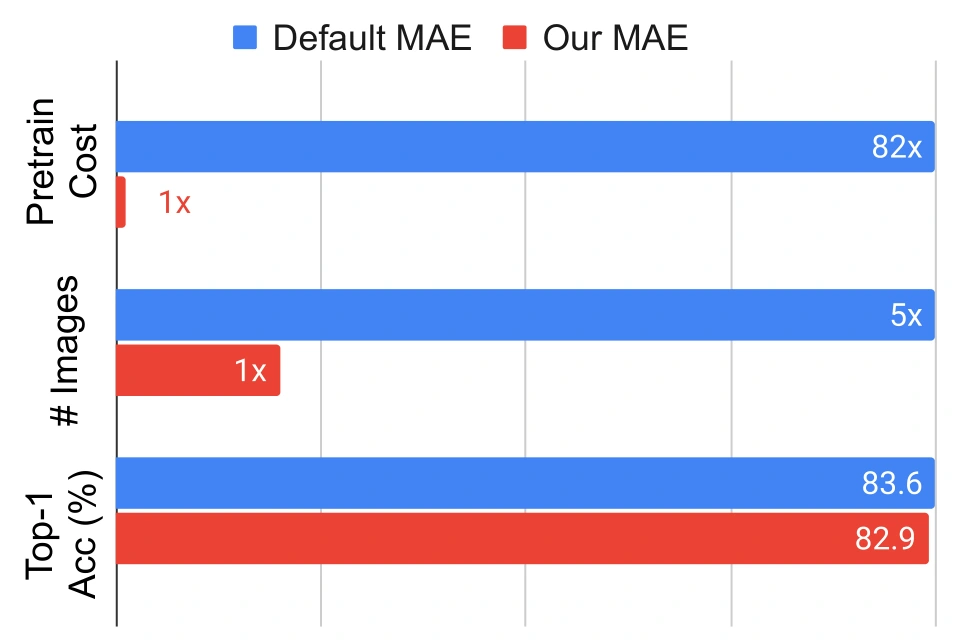
A lighter pre-training recipe unlocks the time and sample efficiency of masked autoencoders.
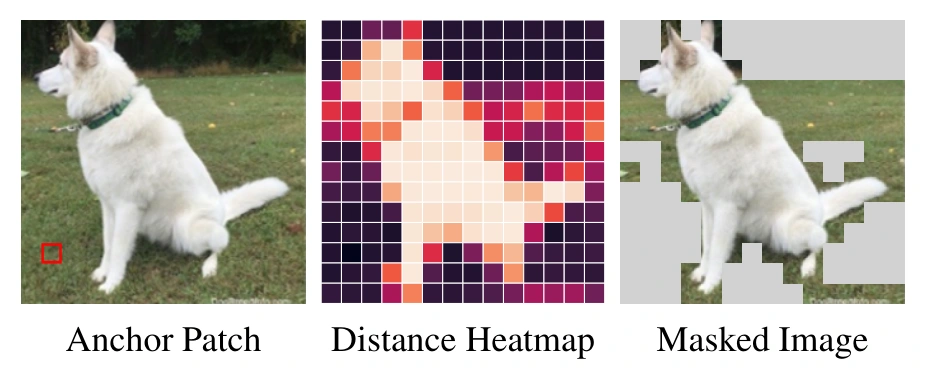
Masking clusters of visually similar patches for efficient vision-language representation learning.
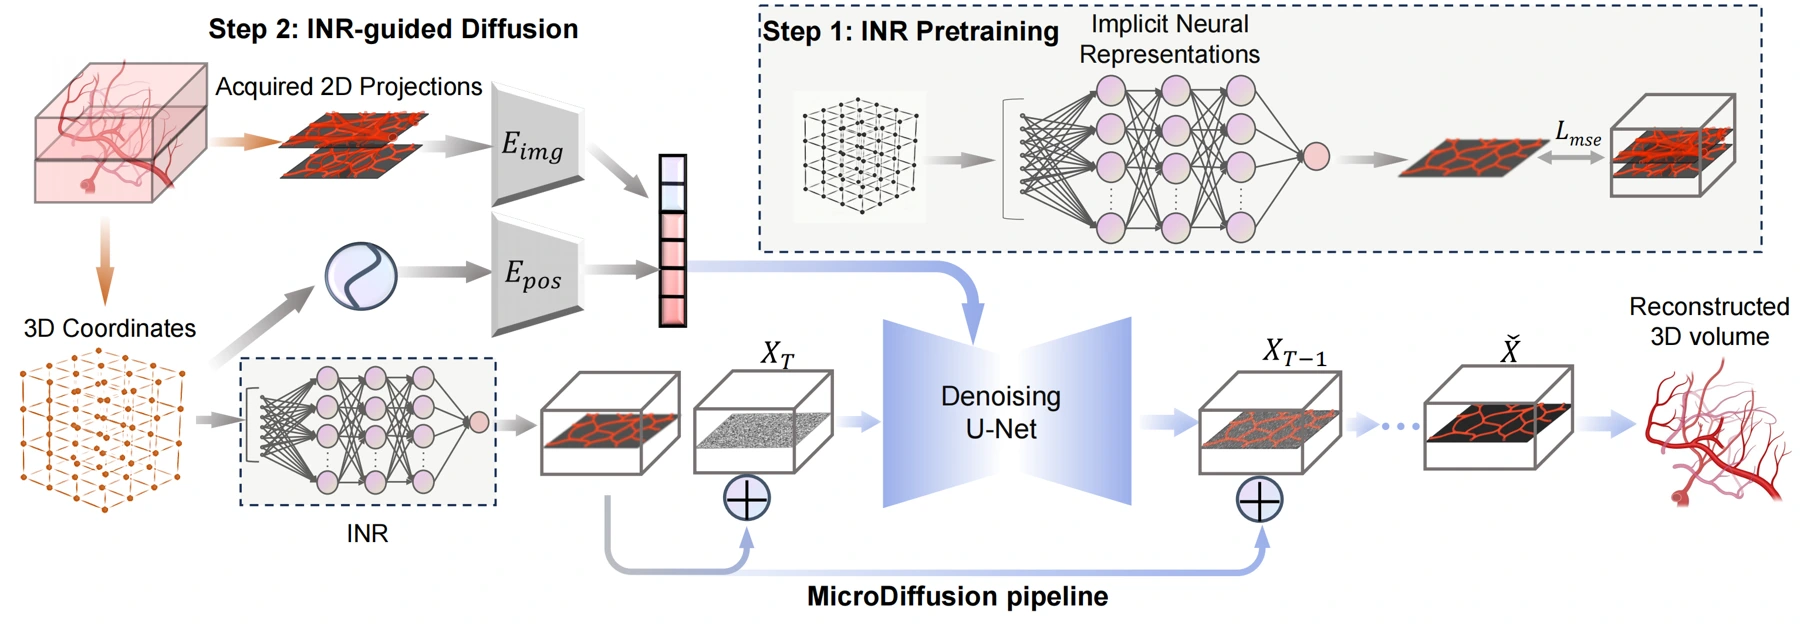
Combining implicit representations and diffusion to recover 3D structure from limited microscopy projections.
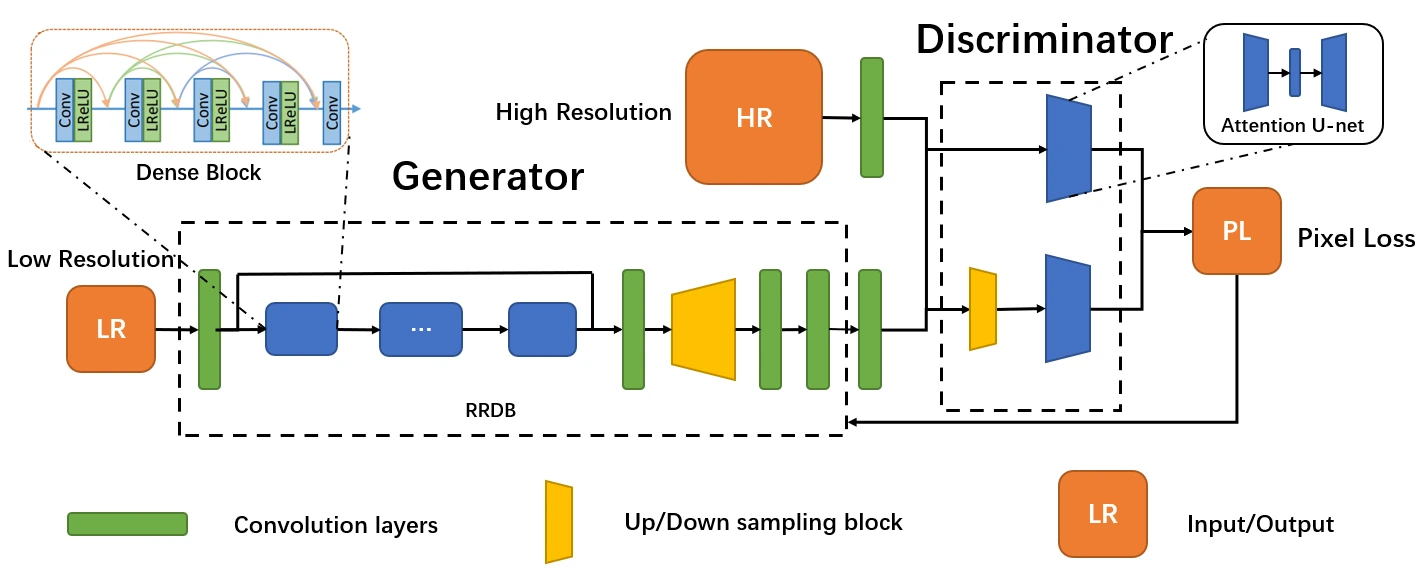
Attention U-Net discriminators for sharper real-world blind super-resolution.
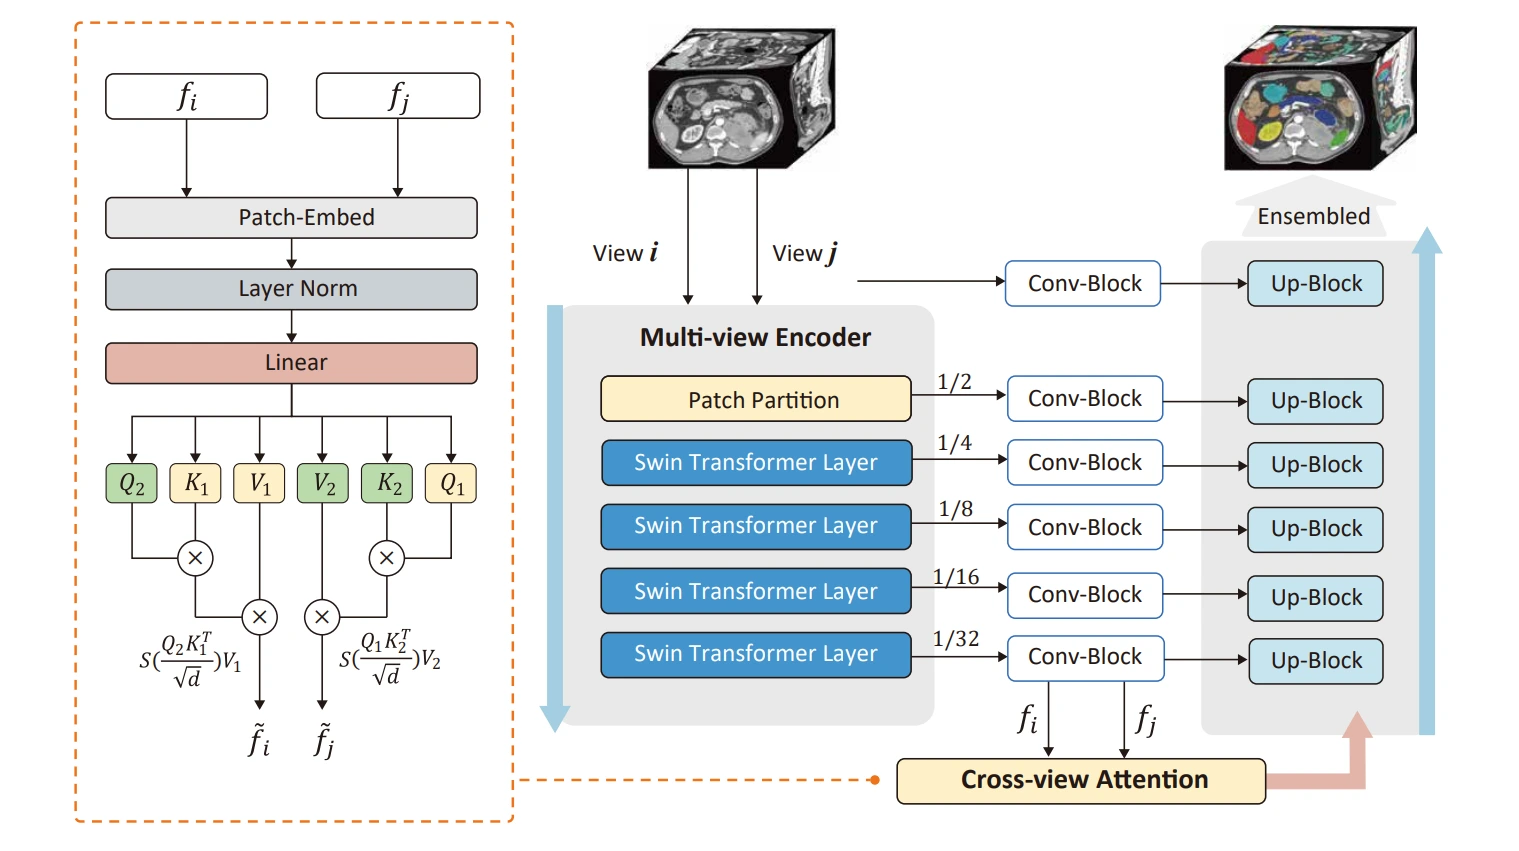
Multi-view masked learning with Swin Transformers for 3D medical image segmentation.
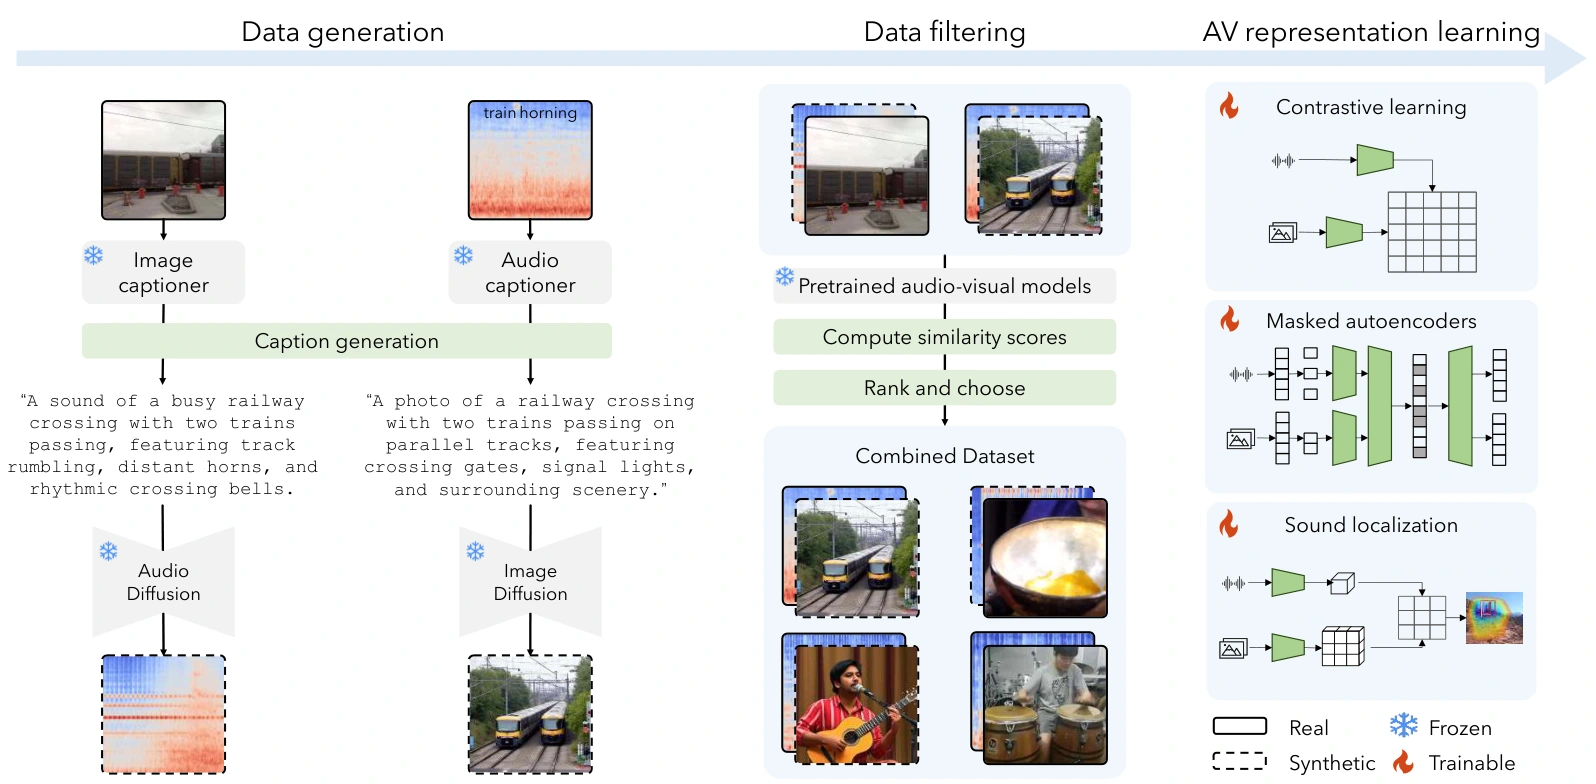
Language-guided cross-modal synthesis for audio-visual representation learning.